Deploying vSphere Pods in VCF 9: A Beginner’s Guide

VCF Automation 9 presents some unique challenges for those of us who grew up with the old Aria Automation model. Change is ever present, though, so this old grumpy guy is learning the new model one practical lesson at a time.

For me, that learning starts with All Apps Organizations and Kubernetes-backed workloads. They are a different way to think about application delivery, and I have found that the quickest way to understand them is to deploy something small, observe what the platform does, and follow the evidence when it does not work as expected.

Today we are going to deploy a vSphere Pod in my VCF 9.1 environment. I will share what I tested, the capacity issue I encountered, and how I exposed the finished workload through a load balancer. Consider this a starting point for the lessons that follow, not a claim that the learning is finished.

Now, on to business.

Before we start clicking buttons, here is the shape of the experiment. We are going to create an All Apps Organization, create a namespace inside its default project, deploy a very small Nginx container, and then expose it through a load balancer. The point is not to build an exciting website. The point is to see which pieces of the platform have to agree before a vSphere Pod can run.

There are three ideas worth keeping in mind as we go. First, a vSphere Pod is a Kubernetes Pod managed by Supervisor, not a vSphere vApp. Second, the namespace carries more responsibility than its name suggests: it is tied to access, capacity, and networking. Third, a successful form submission is only the beginning of the evidence. We still need to see the instance become Ready and reach it from a client network.

We’ll start with a brand new VCF 9 deployment, either real or Holodeck. We’ll use a new All Apps Organization configured with the default settings. Your menu names and available options may vary slightly by release, but the sequence is the important part.

Now let’s see what happens when you try to deploy a pod in the default project called ‘default-project’.

First add a new namespace. Within the project, click Projects -> default-project -> Namespaces -> New. Wait for the namespace to become Active before moving on. That state is not just decorative: it tells us that VCFA has finished creating the namespace and its supporting configuration.
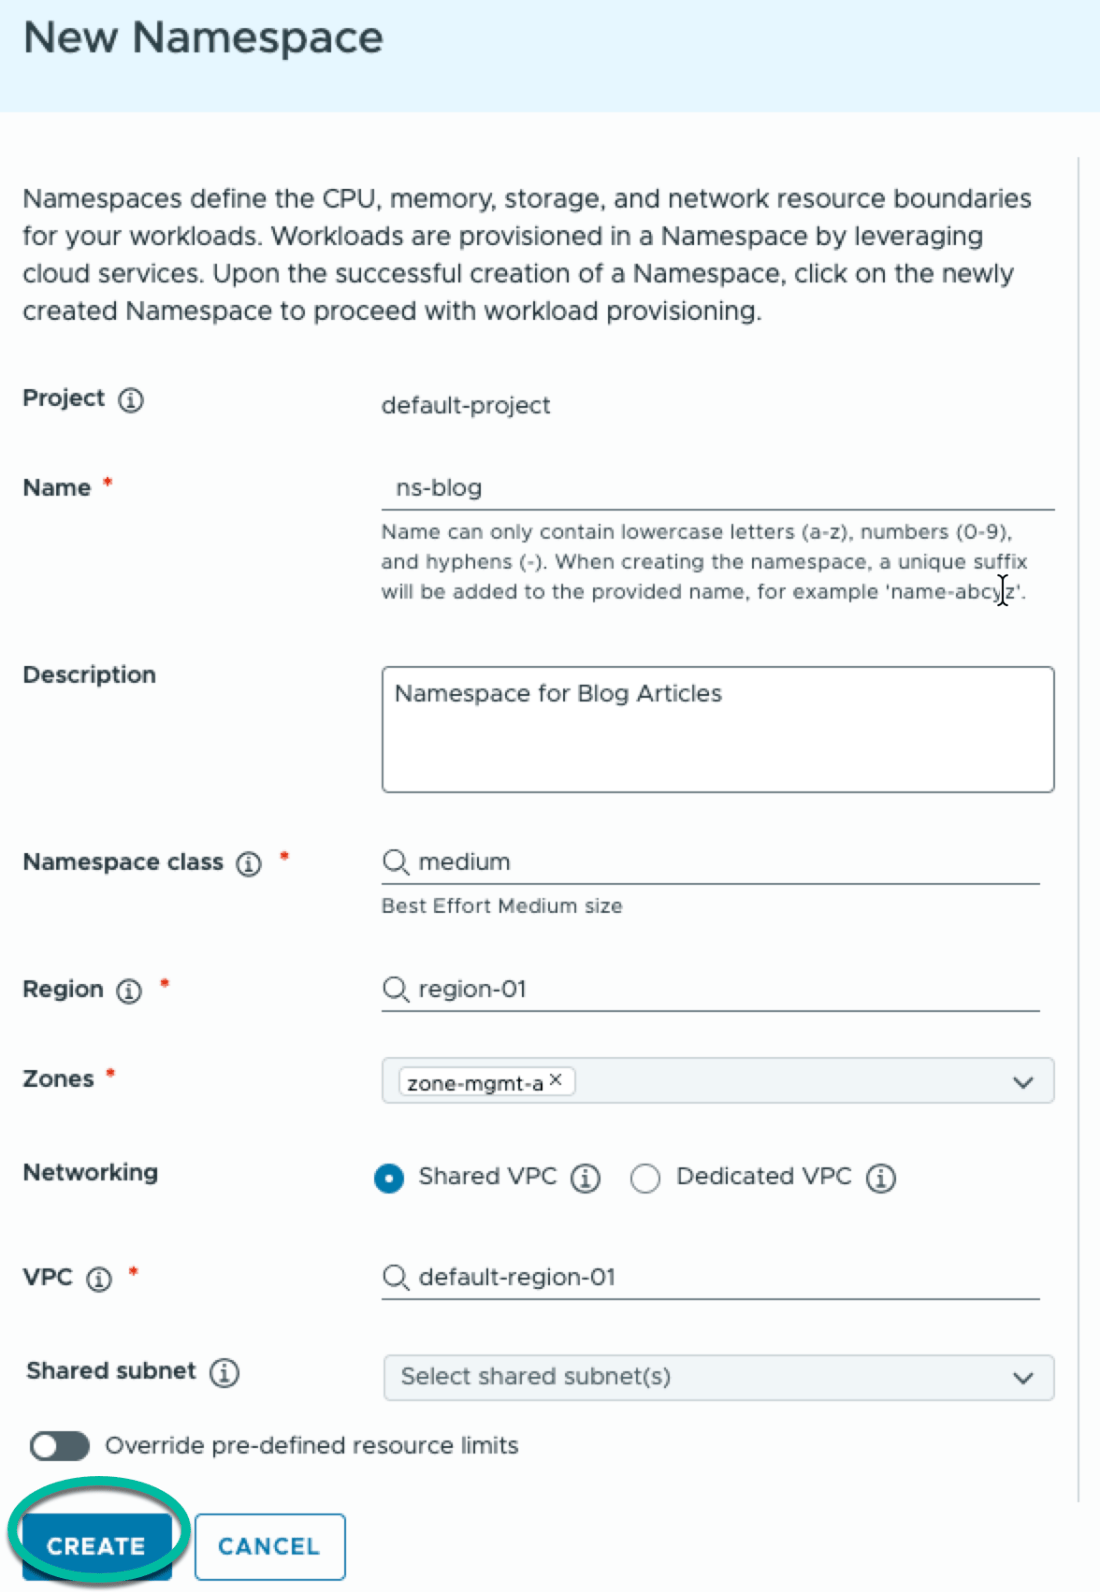
In my Holodeck environment, the namespace was created as ns-blog-2xtdh. After it became Active, I moved on to attempting to deploy a Pod. At this stage, nothing has contacted Harbor and no container has started. We have only established the place where the workload is allowed to live.

Under Build & Deploy, click Select a namespace. After selecting the namespace, you’ll see several resource options. The one in question is Container. Select that and click CREATE NEW INSTANCE.

And now we meet the first useful clue: a yellow warning. This is the point where it is tempting to assume that the new Organization must be broken. It is new, after all. Surely there cannot already be a capacity problem in an empty Organization.

But read the warning closely. It says Insufficient resource reservation. This is not an image-pull error, a Kubernetes application error, or a Harbor error. The platform is telling us that it cannot reserve enough underlying vSphere capacity for the PodVM.

This distinction matters. A container request is eventually backed by vSphere resources, and VCFA checks those resources before the Pod is scheduled. If the request cannot be admitted, the platform never reaches the point where it could pull an image. Changing a registry password at this stage would be a wonderfully energetic way to solve the wrong problem.

Let’s get that fixed. Go back to the namespace through Manage & Govern -> Namespaces, and edit the namespace we just created. There are two related places to inspect: the Organization’s Region Quota and the namespace’s own resource limits.

In the Provider Management Portal, select the Organization and open Region Quota. Then click Edit Reservation next to the relevant Zone. This was the first part that took me a while to find. The setting is not hiding in the container request, because it belongs to the provider and Organization capacity model.
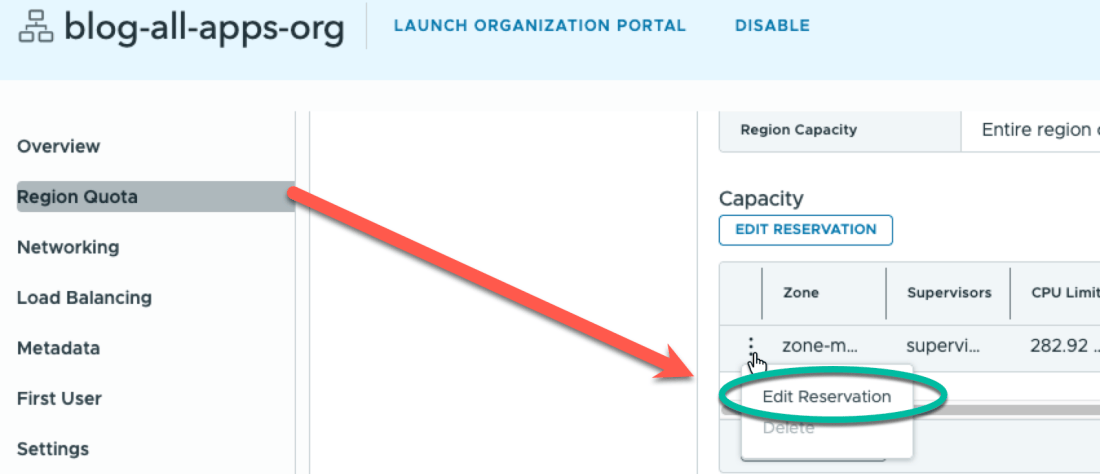
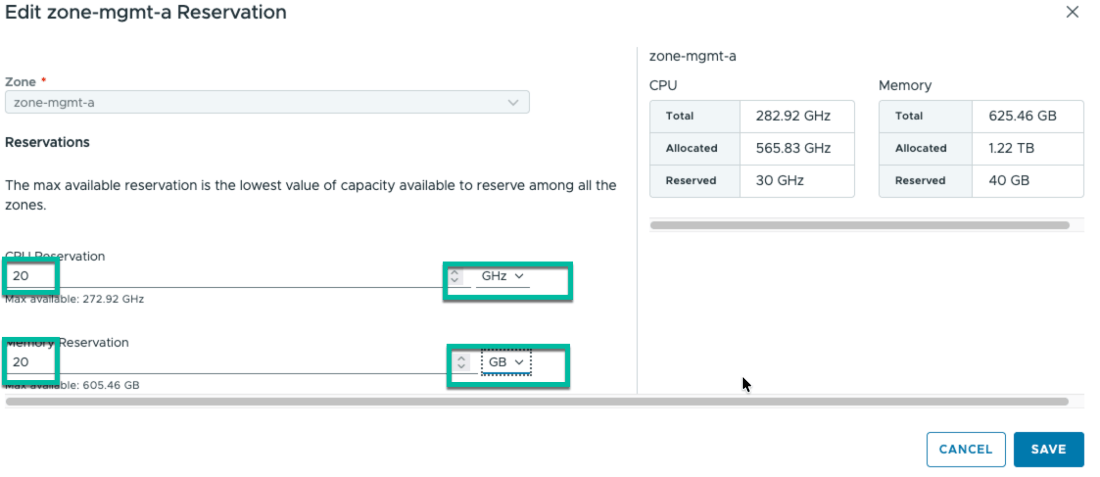
Change the CPU reservation and Memory reservation. I’ll keep the values small-ish, using 19 GHz and 19 GB to get started. These are lab values, not a universal recommendation. The correct numbers depend on the capacity available to the Region, the Organization’s other workloads, the Namespace Class, and the number of replicas you expect to run.

But we still get that warning. There must be somewhere else we need to update. Yep: the Organization quota is only one layer. We still need to update the namespace itself. Click EDIT RESOURCE LIMITS, then update the values.

Do not simply enter the full 20 GHz and 20 GB in both places if the parent reservation is 20 and the platform needs to account for the rest of the allocation. VCFA performs its own capacity calculations and can decide that the child reservation would exceed what the parent can provide. Leave a little room while you are learning the model, and increase the parent and child values deliberately rather than guessing.
Now let’s see if we can deploy that container. That is better, we got past the warning page. We’ll keep most of the values at their defaults for this first pass, but I’ll call out the ones we change. The image below comes from Docker Hub, which keeps this first test focused on scheduling and basic container execution rather than private-registry authentication.

OptionValue
Primary Container Imagedocker.io/library/nginx:alpine
Requested CPU250 millicores
Requested Memory256 MB

If all goes well, you’ll end up with a Ready container instance in a short while. “Ready” is useful, but it has a specific meaning: the platform has admitted the resource and the workload has passed its readiness checks. It does not automatically tell us that an external client can reach the application.

We should also see a Running Instance. At this point, we have proved that VCFA and Supervisor can create and run the workload in the namespace. We have not yet proved that our laptop, browser, or Holodeck client has a route to it.

But woe is me, I can’t reach the Pod to view the page, boring though it may be. Why? The Pod landed on a private VPC network. That is not necessarily a failed deployment. It means the workload has an address on a network that my client cannot directly reach.

This is another useful boundary to remember: a Pod IP is not automatically an externally reachable application endpoint. The namespace determines the Pod’s primary network. To provide a client-facing address, we need a Kubernetes Service and a load-balancer provider, plus routing and firewall policy that allow the client to get there.

Let’s redo this, only this time add a load balancer during the request. We’ll use the same settings until we reach Advanced Setting (Optional). Expand Load Balancer, then click ATTACH LOAD BALANCER. We will expose HTTP port 80 and send it to port 80 in the primary container.

NameValue
Nameblog-lb
New port Namehttp
New port ProtocolTCP
New port Port80
New port Target80
Attach to Primary ContainerChecked (Yes)

Click ADD, then SAVE. Click NEXT to review and confirm your choices, and finally click CREATE CONTAINER INSTANCE.

If all went well, we should have a Ready service shortly. Click the new instance to find the load-balancer address, then browse to it to validate the deployment.

The important difference is that the load balancer gives the client a frontend address while the Pod remains on its workload network. The Service still needs a healthy backend, and the network path still needs to work, so an allocated address is a good sign but not the final test.
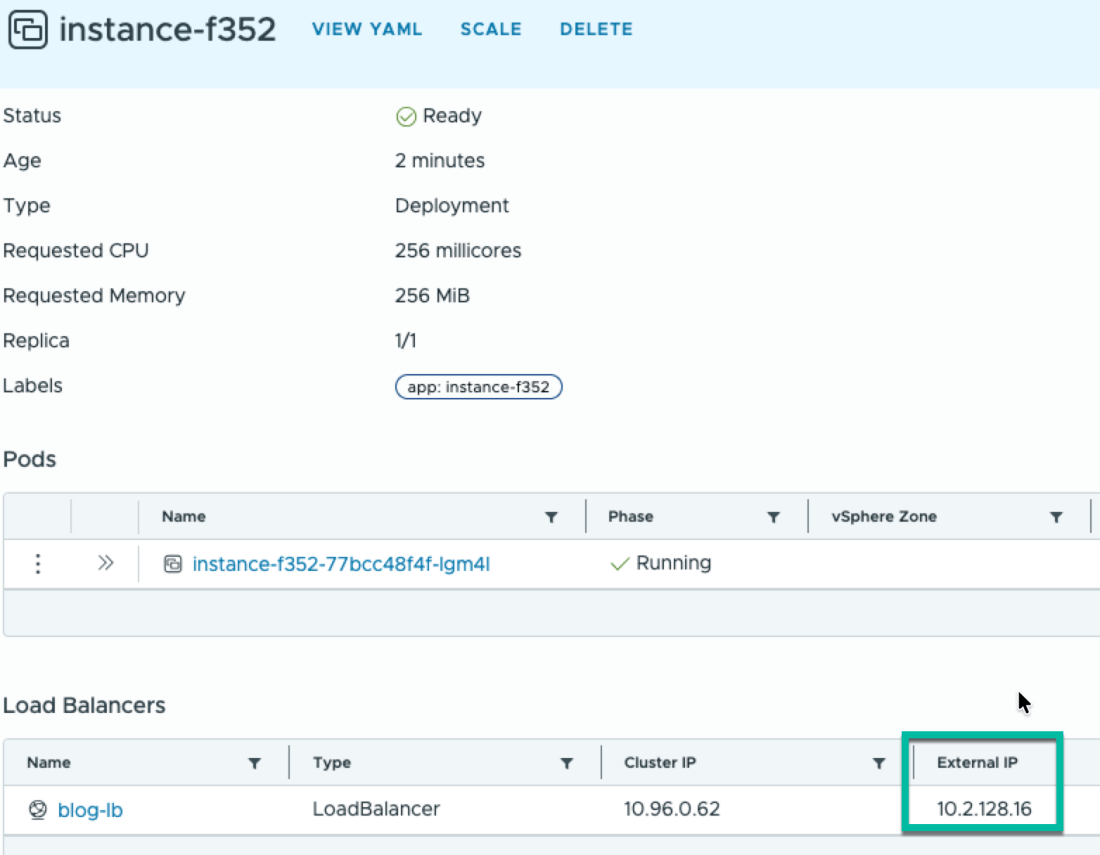
Hey, it worked!
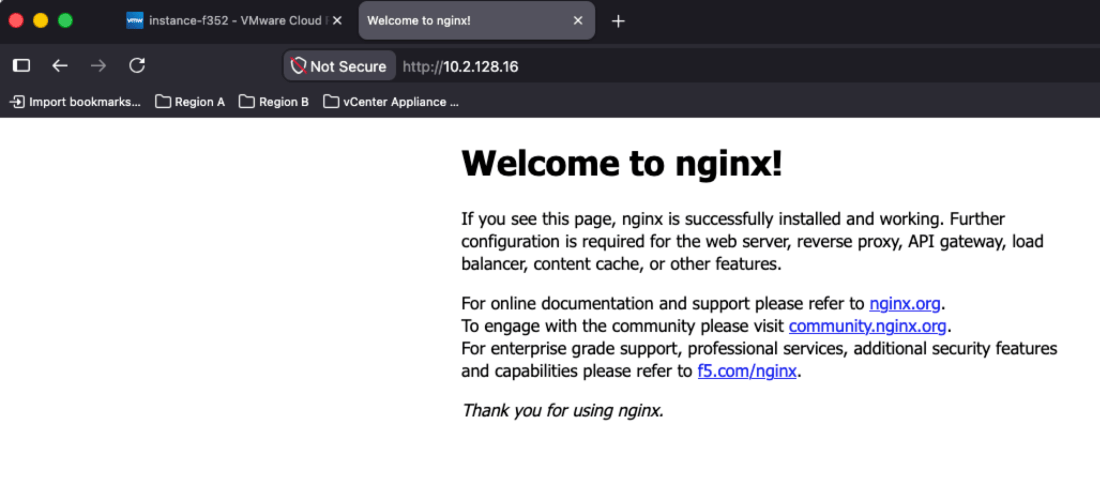
There you go. We started with a new All Apps Organization, discovered that a fresh environment can still have insufficient capacity, corrected the Region Quota and namespace limits, deployed a vSphere Pod, found that its private network was not directly reachable, and then exposed it through a load balancer.

That is a useful first pass because each step tells us something different. The Ready instance proves that the workload was admitted and started. The load-balancer request proves that we asked the platform for an external frontend. The browser test proves that the client can actually reach the application. Those are three different claims, and keeping them separate makes the troubleshooting much easier.

Up next is setting up a local Harbor container registry and using a private image instead of docker.io. That introduces a few new characters: TLS trust, registry credentials, namespace-scoped image-pull Secrets, and the ESXi image-pull path. But that is for another day.

Disclaimer: Some of the stuff you see here has been checked out, tweaked, or even created by AI. Welcome to the new age, folks!

Mastering VCF 9 All Apps Organization Virtual Machine IP Discovery

VCF Automation CCI blueprint VM primary IP address

Getting a VM’s IP address sounds like it should be the easy part of an automation project. In my VCF Automation lab, it turned into one of those small details that consumed far more time than expected.

First some background on my lab environment. Using Holodeck I deployed a single Management Domain, Supervisor, Automation. On top of that I added a single All Apps Organization.

My goal was simple: Deploy an All Apps Organization virtual machine through a CCI.Supervisor.Resource, wait for the VM and its guest network to be ready, and return the assigned IPv4 address as a deployment output. I found an example that pointed me toward status.network.primaryIp4. It was close—but close does not count when a property name is case-sensitive.

My ultimate intent here, is to use that IP address or addresses as part of a three tier application blueprint. But that is another blog.

The path that worked in my environment was:

status.network.primaryIP4

The IP is uppercase. That capitalization was the difference between an empty or unusable value and the address I needed.

Following the VM’s actual status

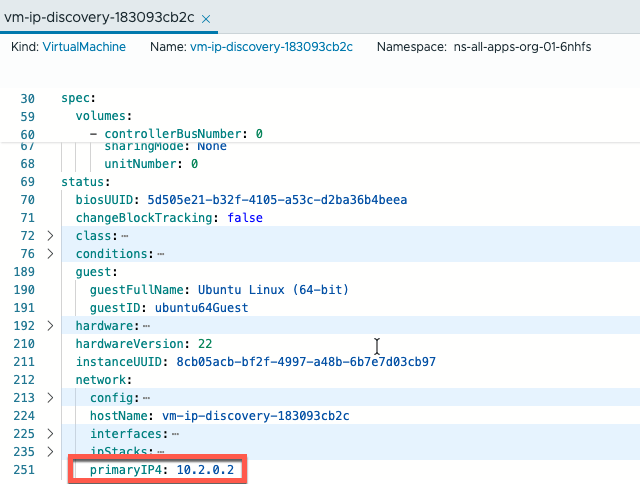
The breakthrough came from looking at the status returned for the deployed VM instead of continuing to guess at the schema. The VM’s status.conditions array showed the conditions it passed through as provisioning progressed. The same status object exposed the network data under:

status:
network:
primaryIP4: 192.0.2.25

The lesson here is simple: Use the object returned by your own VCF Automation and VM Operator version as the source of truth. Blog posts and examples are useful starting points, but a small schema or capitalization difference can break a binding expression.

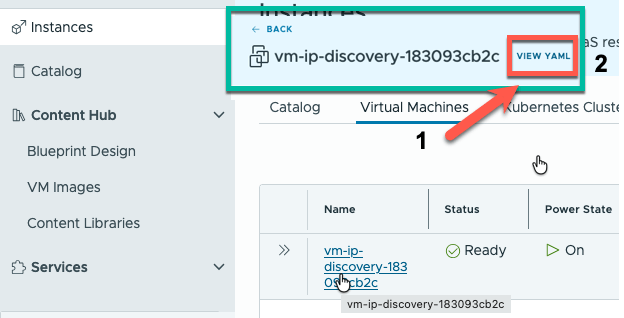
Steps to finding that information.

  1. Deploy the machine
  2. View YAML on the machine page
Steps to finding the deployed machine YAML.
  1. Walk the properties (I collapsed several sections to enhance readability). Here the path to primaryIP4 is status.network.primaryIP4.
All Apps status.network.primaryIP4 path.

How to find the conditions

Follow the same logic as finding primaryIP4. You will find the conditions or stages the machine went through along with the ‘status‘ and 'reason‘.

All Apps Org machine condition or state transition's properties.

Why the wait block matters

Reading the right path is only half of the solution. VCF Automation also needs to wait long enough for the Supervisor resource status to contain the network information.

Broadcom documents a status-collection race in VCF Automation 9.0.x. Without an explicit wait, the resource can be considered created before its reconciled status has been synchronized back to Automation. Broadcom’s minimum recommendation is to wait for VirtualMachineCreated=True.

For my blueprint, I waited for VM creation, VMware Tools, guest network synchronization, and a value matching an IPv4 pattern:

resources:
Supervisor_VM:
type: CCI.Supervisor.Resource
properties:
context: ${resource.Supervisor_Namespace.id}
manifest:
apiVersion: vmoperator.vmware.com/v1alpha5
kind: VirtualMachine
metadata:
name: ${input.vmName}
spec:
# The rest of the sanitized VM manifest goes here.
wait:
timeoutSeconds: 1800
conditions:
- type: VirtualMachineGuestNetworkConfigSynced
status: 'True'
reason: Synced
- type: VirtualMachineCreated
status: 'True'
- type: VirtualMachineTools
status: 'True'
jsonPath:
- path: '{.status.network.primaryIP4}'
regex: \d{1,3}\.\d{1,3}\.\d{1,3}\.\d{1,3}

Return the address as a blueprint output

Once the wait completes, the address can be exposed as a deployment output. With the resource named Supervisor_VM, the binding is:

outputs:
vmIp:
type: string
title: VM primary IPv4 address
value: ${resource.Supervisor_VM.object.status.network.primaryIP4}

Again, the working property is primaryIP4, not primaryIp4.

This output can also be consumed by another resource binding. For example, an application VM could receive a database VM’s address during cloud-init. Make sure the upstream VM’s wait block completes before relying on that value.

Validation

After deploying a new version of the blueprint:

  1. Confirm the deployment completes without a wait timeout.
  2. Inspect the CCI.Supervisor.Resource object and verify that status.conditions includes the expected successful conditions.
  3. Verify that status.network.primaryIP4 contains the VM’s address.
  4. Confirm the deployment output shows the same address.
  5. From an appropriate network location, test the service that should be listening on that address.

The last step matters. VirtualMachineCreated=True, synchronized guest networking, and a populated primaryIP4 prove that the platform has an address for the VM. This does not prove that cloud-init finished successfully or that the application inside the guest is healthy.

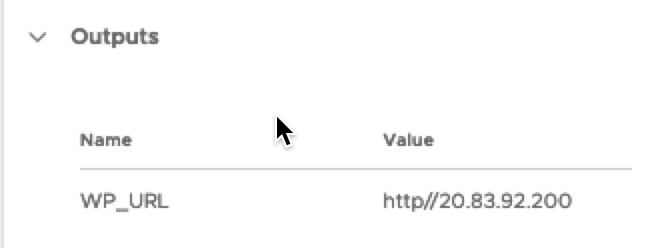
Here is a screenshot of a deployed machine with the output vmIp set to 10.2.0.2.

 Displaying primaryIP4 as an vmIp output

The finished blueprint

The blueprint used in this blog is available here, VCF Automation Supervisor VM IP Discovery on GitHub

Take Aways

  1. Leverage AI to do the heavy research. One of the responses gave me the thought to check that case sensitivity.
  2. AI, also mean’s ‘Ain’t Intelligent’. It WILL send you down the wrong path eventually. As the developer you still need to know what it SHOULD look like in the end. In other words, trust but verify.
  3. Don’t get in a hurry. I worked on this on and off in my ‘spare time’ for a few days. Then finally it clicked at the end.
  4. All Apps Organizations are a new construct for most of us. The available public content and samples are few and far between. Please, Please, Please take some time to share your lessons learned with the community.

References

Nuff for now. Happy automating.

Managing Azure AKS clusters with VMWare Aria Automation

The use case presented to me for POC was to deploy a new Azure AKS cluster then install a basic application. Simple use case, but for those using VRA you know the kubernetes capabilities are all but non existent.

But after digging around and tinkering I figured a CodeStream (now called Pipelines) would probably fit the bill. The pipeline would run a terraform plan to build, and then destroy the deployment later on.

Keeping track of the state file between runs also presented a ‘problem’. After lots of kicking the tires I came up with a way to store the state file securing in an Azure Storage account. The state file in the container is simply the deployment name plus .tfstate. This allowed me to refer to it using day two actions and Event Broker Subscriptions (EBS).

Another issue that came up was deleting ‘codestream.execution’ resources when the deployment is deleted. Since these deployments are handled by terraform I needed another WF which called a pipeline to destroy the deployment when the eventType was DESTROY_DEPLOYMENT.

The files for this article can be found at azure-terraform-blog

Terraform is used to do the heavy lifting. The backend values get replaced with some pipeline inputs in the first pipeline task. The most important one is the deployment name. When destroying the deployment, terraform will pull the current state for that deployment and do its thing.

The CodeStream pipeline (Now Pipelines) uses a custom docker image. It includes the latest version of Terraform (Currently at 1.5.4), AZ CLI, Kubectl, and Helm (for another use case). It is stored on DockerHub as americanbwana/cas-terraform-154:latest.

I didn’t come up with the basic Template. I found this article on vEducate.co.uk. A very good starting point. ‘pipelineTask’ is used by the pipeline to either create (apply) or destroy the deployment. More on that later.

formatVersion: 1
inputs:
  pipelineTask:
    type: string
    title: Pipeline Task
    description: 'Create '
    readOnly: true
    default: create
resources:
  cs.pipeline:
    type: codestream.execution
    properties:
      pipelineId: 2b80427c...
      outputs:
        computed: true
      inputs:
        deploymentName: ${env.deploymentName}
        pipelineTask: ${input.pipelineTask}

vRA doesn’t delete the actual codestream.execution items when you destroy the deployment. A workflow called ‘Terraform delete AKS and Helm deployment’ is called by an Event Broker Subscription (EBS). Make sure to update the ‘codestreamPipelineId’ in the WF variables.

Event Broker Subscription

And finally on to the pipeline. The initialize task copies several variables into a file, which is then sourced by most stages. Terraform apply is only fired if the pipelineTask = ‘create’. And Terraform destroy is only fired when pipelineTask = ‘destroy’.

Pipeline

‘Get Service IP’ is also only fired if the pipelineTask = ‘create’. This task will get the IP address of WordPress and export it back to vRA.

Terraform Output
Assembler Output

Nuff for now. Happy coding.

CyberArk Ansible Integration

As an alternative to vRA Cloud Secrets

Well its been a while since I posted anything. To be honest, this site and posts were used to support my vExpert applications, but apparently blog content doesn’t count anymore. So…. now that I’m free from that obligation, I can just post because I want to.

This article details my efforts to understand how CyberArk and Ansible work together. My particular use case is to replace vRA Cloud secrets with variables stored in CyberArk. More specifically the issue with vRA secrets is they are limited to a single Project. This doesn’t work to well for a company with more than one project. Basically have one secret (mysecret) per project. Or if you have 10 projects, 10 secrets named mysecret (one for each project).

Now down to business. The first thing is to setup CyberArk following the instructions from their Quick Start tutorial. The basic setup is done by step 6, no real need to go past that unless you want to. A couple of notes here. First the Master Key (Step 2) and Admin api_key (Step 5) are saved to a text file on your docker host. And secondly, by default the SSL generated by the installer uses localhost, proxy, and 127.0.0.1 as the SAN. You can change this in conjur-quickstart/conf/tls/tls.conf. I’ll be using the default proxy as the hostname, along with some entries in /etc/hosts on my Mac and Ansible host.

Next I installed Cyberark CLI on my Mac. The instructions are available here. Note is is only supported on Windows, RHEL and Mac.

The setup file on my Mac for ~.conjurcli looks like this.

cert_file: /Users/me/conjur-server.pem
conjur_account: myConjurAccount
conjur_url: https://proxy:8443

Now to define some CyberArk Conjur (conjur) policy files. The first was to define a new clean branch for my ansible policies. I called it mybranch (Hey it was Friday and I already used my weekly good braincell quota). I even used a creative name, ‘create-ansible-branch.yaml’.

- !policy
  id: mybranch

And to apply it (assuming you’ve already logged in as Admin).

mymac>conjur policy replace -b root -f create-ansible-branch.yaml
mymac>conjur list
[
    "myConjurAccount:policy:mybranch",
    "myConjurAccount:policy:root"
]

Now on to defining the ansible host (ansible2)

- !layer

- !host ansible2

- !grant
  role: !layer
  member: !host ansible2

mymac>conjur policy load -b mybranch -f ansible2-host-policy.yaml

The result will contain an api_key for the new host. You’ll probably want to copy this into your scratch pad.

  {
      "created_roles": {
          "myConjurAccount:host:mybranch/ansiblehost": {
              "id": "myConjurAccount:host:mybranch/ansiblehost",
              "api_key": "1xgpkp02d8etyz2zb........" # <--- api_key
          }
      },
      "version": 2
  }

Now to create a new group, variable, and grant ansible2 permissions.

# Declare the secrets which are used to access the database
- &variables
  - !variable password2

# Define a group which will be able to fetch the secrets
- !group secrets-users

- !permit
  resource: *variables
  # "read" privilege allows the client to read metadata.
  # "execute" privilege allows the client to read the secret data.
  # These are normally granted together, but they are distinct
  #   just like read and execute bits on a filesystem.
  privileges: [ read, execute ]
  roles: !group secrets-users
# Entitlements

- !grant
  role: !group secrets-users
  member: !layer /mybranch

mymac>conjur policy load -b mybranch -f ansible2-access-policy.yaml
### Set the password variable value
mymac>conjur variable set -i mybranch/password2 -v "HelloWorld"

Our work with CyberArk is done for the time being. Now on to your ansible host. Here the assumption is our ansible host is setup properly. First install the Cyberark.conjur collection.

ubunutu@ansible2$ansible-galaxy collection install cyberark.conjur

Now to define some files on your ansible host. The file names and content are shown below. You can figure out how to get the contents of conjur.pem.

/etc/conjur.conf

account: myConjurAccount
appliance_url: https://proxy:8443
cert_file: /etc/conjur.pem
netrc_path: /etc/conjur.identity
plugins: []

/etc/conjur.identity

machine https://proxy:8443/authn
    login host/mybranch/ansible2
    password gybp2n1wssmh1fr8n5k27.........


/etc/conjur.pem

-----BEGIN CERTIFICATE-----
.......
-----END CERTIFICATE-----

Almost there, now to define and run a basic ansible playbook. And by basic, I mean basic.

# get_conjur_var.yaml

---
- hosts: localhost
  tasks:
  - name: Lookup variable in Conjur
    debug:
      msg: "{{ lookup('cyberark.conjur.conjur_variable', 'mybranch/password2') }}"

ubunutu@ansible2$ansible-playbook get_conjur_var.yaml

.... 
ok: [localhost] => {
    "msg": "HelloWorld"
}
....

The next article will demonstrate how to use this with vRA cloud to replace all those repetitive secrets (Per project, Yuk!)

vRO Action PowerShell Zip importing and use

One of my current tasks is to leverage vRealize Automation Orchestrator to meet the following use case.

  • Get the next available subnet from InfoBlox
  • Reserve the gateway and other IP’s in the new subnet
  • Create a new NSX-T segment
  • Create new NSX-T security groups
  • Discover the new segment in vRealize Automation Cloud
  • Assign the new InfoBlox to the discovered Fabric Network
  • Create a new Network Profile in vRA Cloud

This weeks goal was to get the InfoBlox part working. Well I had it working two years ago, but couldn’t remember how I did it (CRS).

Today I’ll discuss how to use vRO to get the next available subnet from InfoBlox. The solution uses a PSM I build, along with the PowerShell script which actually does the heavy lifting. One key difference between my solution and the one from VMware’s documentation is the naming of the zip file. This affects how to import and use it in vRO.

The code used in this example is available in this GitHub repo. Clone the repo, then run the following command to zip up the files.

zip -r -x ".git/*" -x "README.md" -X nextibsubnet.zip .

Next import the zip file into vRO, add some inputs, modify the output, then finally run it.

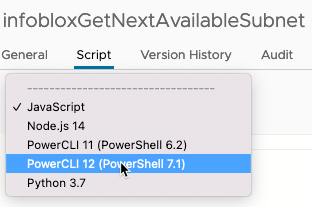
Within vRO, add a new Action. Then change the script type to “PowerCli 12 (PowerShell 7.1).

PowerShell Script Type

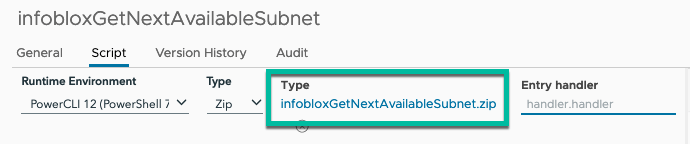
Change the Type to ‘Zip’ by clicking on the dropdown under ‘Type’ and selecting ‘Zip’

Click ‘Import’, then browse to the folder containing the zip file from earlier in the article.

You will notice the name is not ‘nextibsubnet.zip’ but InfobloxGetNextAvailableSubnet.zip. The imported zip assumes the name of the vRO Action.

Now the biggest difference between my approach and the VMware way. If you look at the cloned folder you will see a file named ‘getNextAvailableIbSubnet.ps1’. The VMware document called this file ‘handler.ps1’. Instead of putting in ‘handler.handler’ in ‘Entry Handler’, I’ll use ‘getNextAvailableIbSubnet.handler. This tells vRO to look inside ‘getNextAvailableIbSubnet.ps1’ for a function called ‘handler’.

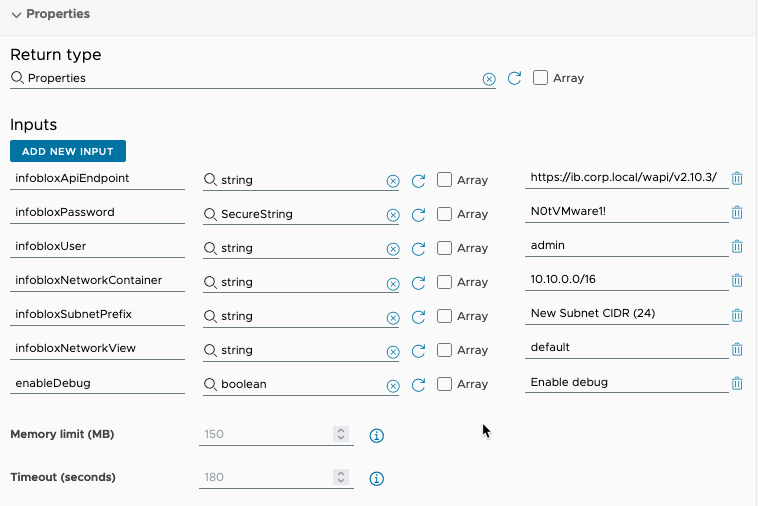
Next we need to change the return type to Properties, and add a few inputs.

Save and run. And if everything is in order, you should get the next InfoBlox subnet from 10.10.0.0/24. The results from the action run.

So there you go. Now on to the next adventure.

Custom vSphere Template import into AWS as AMI

My current customer asked if they could use the same vSphere template as an AWS AMI. The current vSphere template has a custom disk layout to help them troubleshoot issues. The default single disk layout for AMI’s actually hinders their troubleshooting methodology.

Aside from the custom disk layout, I know VMtools would have to be replaced with cloud-init. Sure no problem. RIGHT! Well actually it wasn’t that hard.

Well I was finally able get it to work, and learned a bunch along the way. Those lessons include,

  • The RHEL default DHCP client is incompatible with AWS.
  • EFI bios is only supported in larger, more expensive instances.
  • AWS VM image import.
  • Make sure to enable ‘disable_vmware_customization’, if that made sense.

Requirements

  • AWS roles, policies and permissions per this document.
  • S3 bucket (packer-import-example) to store the VMDK until it is imported.
  • Basic IAM user (packer) with the correct permissions assigned (see above).
  • vSphere environment to build the image.
  • A RHEL 8.x DVD ISO for installation.
  • HTTP repo to store the kickstart file.

Now down to brass tacks. To be honest it took lots of trial and error (mostly error) to get this working right. For example, on one pass Cloud-Init wouldn’t run on the imported AMI. After looking at cloud.cfg I noticed ‘disable_vmware_customization’ was set to false instead of ‘true’. Another error occurred when my first import attempt failed as the machine did not have a ‘DHCP client’. That was odd as it booted up fine in vSphere and got an IP Address. Apparently AWS only supports certain DHCP clients. Go figure.

Eventually the machine booted properly in AWS, with the user-data applied correctly. The working user-data is in the repo’s cloud-init directory.

And my super simple vRAC blue print even worked. This simple BP adds a new user, assigns a password, and grants it SUDO permissions.

Successful vRA Cloud Deployment

A couple of notes on the packer amazon-import post processor. Those include,

  • The images are encrypted by default, even tho the default for ‘ami_encrypt’ is false by default.
  • ‘ami_name’ requires the AWS permission of ec2:CopyImage on the policy for the import role.
  • Don’t use the default encryption key if you wish to share this. You’ll need a Customer Managed Key (CMK). The import role (vmimport) will need to be a key user. You can set this with ‘ami_kms_key’ set to the Id of the CMK (i.e., ebea!!!!!!!!-aaaa-zzzz-xxxxxxxxxxxxxx)
  • The CMK needs to be shared with the target customer before sharing the AMI. ‘ami_org_arns’ allows you to set the organizations you’d like to share the AMI with.
  • There are lots of import options, you can check them out here.

This working example, plus others I’ve been working are available in this github repo.

Now onto another vRAC adventure.

Packer HCL and PVSCSI drivers

Just this last week I was updating an old Packer build configuration from JSON to HCL. But for the life of me could not get a new vSphere Windows 2019 machine to find a disk attached to Para Virtualized disk controller.

I repeatedly received this error after the machine new machine booted.

Error

In researching error 0x80042405 in C:\Windows\pather\setuperr.log, I found it simply could not find the attached disk.

setuperr.log

After some research I determined the PVSCSI drivers added to the floppy disk where not being discovered. Or more specifically the new machine didn’t know to search the floppy for additional drivers.

I finally found a configuration section for my autounattend.xml file which would fix it after an almost exhaustive online search.

The magic section reads as follows.

<unattend xmlns="urn:schemas-microsoft-com:unattend">
    <settings pass="windowsPE">        
       <component name="Microsoft-Windows-PnpCustomizationsWinPE" processorArchitecture="amd64" publicKeyToken="31bf3856ad364e35" language="neutral" versionScope="nonSxS" xmlns:wcm="http://schemas.microsoft.com/WMIConfig/2002/State" xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance">
            <DriverPaths>
                <PathAndCredentials wcm:action="add" wcm:keyValue="A">
                    <!-- pvscsi-Windows8.flp -->
                    <Path>A:\</Path>
                </PathAndCredentials>
            </DriverPaths>
        </component>
...
    </settings>

After adding this section, the new vSphere Windows machine easily found the additional drivers.

This was tested against Windows 2019 in both AWS and vSphere deployments.

The vSphere deployment took an hour, mostly waiting for the updates to be applied. AWS takes significantly less time as I’m using the most recently updated image they provide.

The working files are located in the packer-hcl-vsphere-aws github repo.

Code Stream Nested Esxi pipeline Part 2

In this second part, I’ll discuss the actual Code Stream pipeline.

As stated before, the inspiration was William Lams wonderful Power Shell scripts to deploy a nested environment from a CLI. His original logic was retained as much as possible, however due to the nature of K8S a few things had to be changed. I’ll try to address those as they come up.

After some thought I decided to NOT allow the requester to select the amount of Memory, vCPU, or VSAN size. Each Esxi host has 24G of Ram, 4 vCPU, and contributes a touch over 100G to the VSAN. The resulting cluster has 72G of RAM, 12 vCPUs and a roughly 300G VSAN. Only Standard vSwitches are configured in each host.

The code, pipeline and other information is available on this github repo.

Deployment of the Esxi hosts is initiated by ‘deployNestedEsxi.ps1’. There are few changes from the original script.

  1. The OVA configuration is only grabbed once. Then only the specific host settings (IP Address and Name are changed.
  2. The hosts are moved into a vApp once built.
  3. The NetworkAdapter settings are performed after deployment.
  4. Persisted the log to /var/workspace_cache/logs/vsphere-deployment-$BUILDTIME.log.

Deployment of the vCSA is handled by ‘deployVcsa.ps1’ Some notable changes from the original code include.

  1. Hardcoded the SSO username to administrator@vsphere.local.
  2. Hardcoded the size to ‘tiny’.
  3. Save the log file to /var/workspace_cache/logs/NestedVcsa-$BUILDTIME.log.
  4. Save the configuration template to /var/workspace_cache/vcsajson/NestedVcsa-$BUILDTIME.json.
  5. Move the VCSA into the vApp after deployment is complete.

And finally ‘configureVc.ps1’ sets up the Cluster and VSAN. Some changed include.

  1. Hardcoded the Datacenter name (DC), and Cluster (CL1).
  2. Import the Esxi hosts by IP (No DNS records setup for the hosts or vCenter).
  3. Append the configuration results to /var/workspace_cache/logs/vsphere-deployment-$BUILDTIME.log.

So there you go, down and simple Code Stream pipeline to deploy a nested vSphere environment in about an hour.

Stay tuned. The next article will include an NSX-T deployment.

vRA Cloud Day 2 Resource Action using a Polyglot workflow

One of my peers came up with an interesting use case today. His customer wanted to mount an existing disk on a virtual machine using a vRA Cloud day 2 action.

I couldn’t find an out of the box workflow or action on my vRO, which meant I had to do this thing from scratch.

After a quick look around I found a PowerCli cmdlet (New-Hardisk) which allowed me to mount an existing disk.

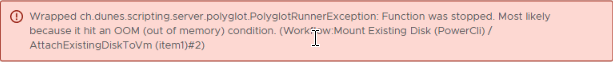
My initial attempts to just run it as a scriptable task resulted in the following error.

Hmm, so how do you increase the memory in a scriptable task? Simple, you can’t. Thus I had to move the script into an action, which does allow me to increase the memory. After some tinkering I found that 256M was sufficient to run the code.

function Handler($context, $inputs) {
    # $inputs:
    ## vmName: string
    ## vcName: string (in configuration element)
    ## vcUsername: string (in configuration element)
    ## vcPassword: secureString (in configuration element)
    ## diskPath: string. Example in code. 
    # output:
    ## actionResult: Not used
    $inputsString = $inputs | ConvertTo-Json -Compress

    Write-Host "Inputs were $inputsString"

    $output=@{status = 'done'}

    # connect to viserver
    Set-PowerCLIConfiguration -InvalidCertificateAction:Ignore -Confirm:$false
    Connect-VIServer -Server $inputs.vcName -Protocol https -User $inputs.vcUsername -Password $inputs.vcPassword

    # Get vm by name
    Write-Host "vmName is $inputs.vmName"
    $vm = Get-VM -Name $inputs.vmName

    # New-HardDisk -VM $vm -DiskPath "[storage1] OtherVM/OtherVM.vmdk"
    $result = New-HardDisk -VM $vm -DiskPath $inputs.diskPath 
    Write-Host "Result is $result"

    return "It worked!"
}

Looking at the code, you will notice an input of vmName (used by PS to find the VM). Getting the vmName is actually pretty stupid simple using JavaScript. My first task in the WF takes care of this.

// get the vmName
// $inputs.vm
// output: vmName
vmName = vm.name

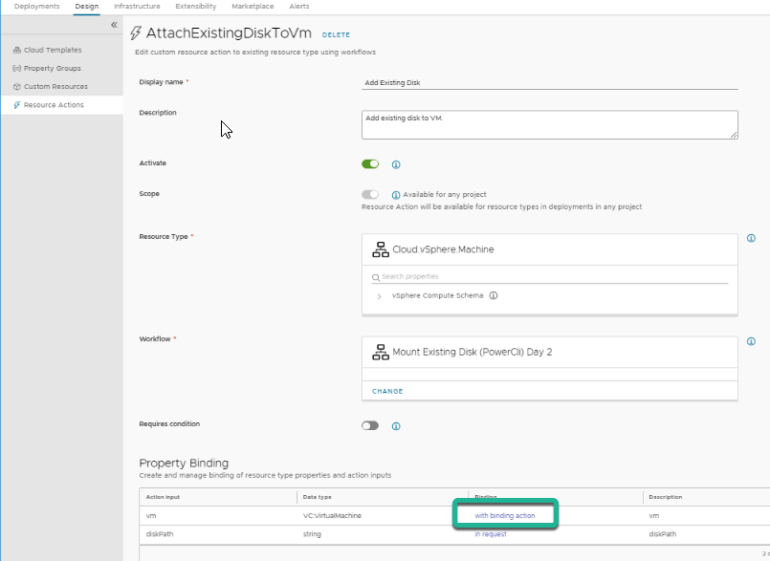
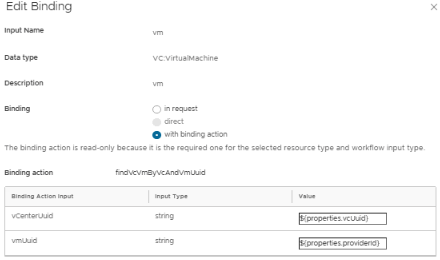
The next step was to setup a resource action. The settings are shown in the following snapshot. Please note the setting within the green box. ‘vm’ is set with a binding action.

Changing the binding is fairly simple. Just click the binding link, then change the value to ‘with binding action’. The default values work just fine.

The disk I used in the test was actually a copy of another VM boot disk. It was copied over to another datastore, then renamed to ‘ExistingDisk2.vmdk’. The full diskPath was [dag-nfs] ExistingDisk/ExistingDisk2.vmdk.

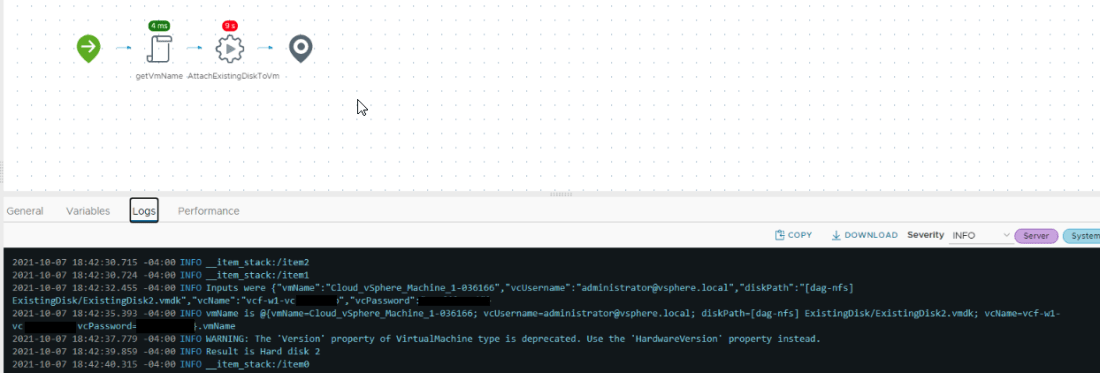
Running the day 2 action on deployed machine seemed to work, as the WF logs show.

So there you have a basic PolyGlot vRO workflow using PowerCli and JavaScript.

I trust this quick blog was helpful in some small way.

Changing vRealize Automation Cloud Proxy internal network ranges

My current customer needs to use 172.18.0.0/16 for their new VMWare Cloud on AWS cluster. However we tried this in the past and were getting a “NO ROUTE TO HOST” error when trying to add the VMC vCenter as a cloud account.

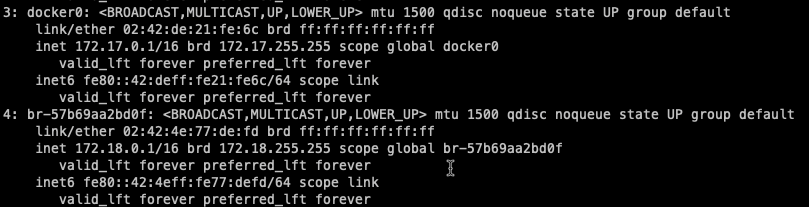
The problem was eventually traced back to the ‘on-prem-collector’ (br-57b69aa2bd0f) network in the Cloud Proxy which also uses the same subnet.

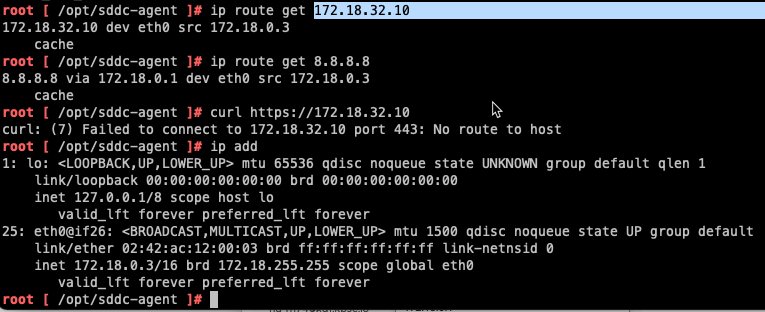
Let’s say the vCenters IP is 172.18.32.10. From inside cloudassembly-sddc-agent container, I try to connect to the vCenter. Eventually getting a ‘No route to host’ error. Can anyone say classic overlapping IP space?

We reached out to our VMWare Customer Success Team and TAM, who eventually provided a way to change the Cloud Proxy docker and on-prem-collector subnets.

Now for the obligatory warning. Don’t try this in production without having GSS sign off on it.

In this example I’m going to change the docker network to 192.168.0.0/24 and the on-prem-collector network to 192.168.1.0/24.

First to update the docker interface range.

Add the following two lines to /etc/docker/daemon.json. Don’t forget to add the necessary comma(s). Then save and close.

{
  "bip": "192.168.0.1/24",
  "fixed-cidr": "192.168.0.1/25"
}

Restart the docker service.

# systemctl restart docker

Now onto the on-prem-collector network.

Check to see which containers are using this network with docker network inspect on-prem-collector. Mine had two, cloudassembly-sddc-agent, cloudassembly-cmx-agent.

# docker network inspect on-prem-collector
[
    {
        "Name": "on-prem-collector",
        "Id": "57b69aa2bd0f694d76cc553769321deebcdb79e009e0964c4b5cc47aadb14684",
        "Created": "2021-02-10T16:05:21.953266873Z",
        "Scope": "local",
        "Driver": "bridge",
        "EnableIPv6": false,
        "IPAM": {
            "Driver": "default",
            "Options": {},
            "Config": [
                {
                    "Subnet": "172.18.0.0/16",
                    "Gateway": "172.18.0.1"
                }
            ]
        },
        "Internal": false,
        "Attachable": false,
        "Ingress": false,
        "ConfigFrom": {
            "Network": ""
        },
        "ConfigOnly": false,
        "Containers": {
            "05105324cff757d76de9e2f535cfb72d2e96094a630561aa141a40aa04095f00": {
                "Name": "cloudassembly-cmx-agent",
                "EndpointID": "8f6717a969b5a1edfea37b9e3d77565c38419de18774bebf4c3981e41c1ad017",
                "MacAddress": "02:42:ac:12:00:03",
                "IPv4Address": "172.18.0.3/16",
                "IPv6Address": ""
            },
            "b227cf1add6caca415b88f927fb10982b0cd846f71548f95071b65330e4024e1": {
                "Name": "cloudassembly-sddc-agent",
                "EndpointID": "4f802a81e0a5dfe50ca39675a5b5106a5fb647198f3bfa898f4f62793baad448",
                "MacAddress": "02:42:ac:12:00:02",
                "IPv4Address": "172.18.0.2/16",
                "IPv6Address": ""
            }
        },
        "Options": {},
        "Labels": {}
    }
]

Disconnect those two machines from the on-prem-collector network.

# docker ps
CONTAINER ID        IMAGE                                                                          COMMAND                  CREATED             STATUS              PORTS                      NAMES

05105324cff7        symphony-docker-external.jfrog.io/vmware/cloudassembly-cmx-agent:207           "./run.sh --lemansDa…"   4 days ago          Up 5 minutes        127.0.0.1:8004->8004/tcp   cloudassembly-cmx-agent

b227cf1add6c        symphony-docker-external.jfrog.io/vmware/cloudassembly-sddc-agent:4cda576      "./run.sh --lemansDa…"   4 days ago          Up 5 minutes        127.0.0.1:8002->8002/tcp   cloudassembly-sddc-agent

# docker network disconnect on-prem-collector b227cf1add6c
# docker network disconnect on-prem-collector 05105324cff7
# docker network inspect on-prem-collector
[
    {
        "Name": "on-prem-collector",
        "Id": "57b69aa2bd0f694d76cc553769321deebcdb79e009e0964c4b5cc47aadb14684",
        "Created": "2021-02-10T16:05:21.953266873Z",
        "Scope": "local",
        "Driver": "bridge",
        "EnableIPv6": false,
        "IPAM": {
            "Driver": "default",
            "Options": {},
            "Config": [
                {
                    "Subnet": "172.18.0.0/16",
                    "Gateway": "172.18.0.1"
                }
            ]
        },
        "Internal": false,
        "Attachable": false,
        "Ingress": false,
        "ConfigFrom": {
            "Network": ""
        },
        "ConfigOnly": false,
        "Containers": {},
        "Options": {},
        "Labels": {}
    }
]

Delete the on-prem-collector network, then re-add using the new subnet (using 192.168.1.0/24)

# docker network rm on-prem-collector
on-prem-collector
# docker network create --subnet=192.168.1.0/24 --gateway=192.168.1.1 on-prem-collector
47e3d477a87c4459f57e3a7305754b1d91e4d13e645ad4c160de5b8e64fede1a

Reconnect the two containers to the new docker network.

# docker network connect on-prem-collector 05105324cff7
# docker network connect on-prem-collector b227cf1add6c
# 
# docker network inspect on-prem-collector
[
    {
        "Name": "on-prem-collector",
        "Id": "47e3d477a87c4459f57e3a7305754b1d91e4d13e645ad4c160de5b8e64fede1a",
        "Created": "2021-05-18T15:58:55.019732144Z",
        "Scope": "local",
        "Driver": "bridge",
        "EnableIPv6": false,
        "IPAM": {
            "Driver": "default",
            "Options": {},
            "Config": [
                {
                    "Subnet": "192.168.1.0/24",
                    "Gateway": "192.168.1.1"
                }
            ]
        },
        "Internal": false,
        "Attachable": false,
        "Ingress": false,
        "ConfigFrom": {
            "Network": ""
        },
        "ConfigOnly": false,
        "Containers": {
            "05105324cff757d76de9e2f535cfb72d2e96094a630561aa141a40aa04095f00": {
                "Name": "cloudassembly-cmx-agent",
                "EndpointID": "34df13b0accf2f561e0226918a7e84d02995a25f4cc3969758a913a3f6c4e8bb",
                "MacAddress": "02:42:c0:a8:01:02",
                "IPv4Address": "192.168.1.2/24",
                "IPv6Address": ""
            },
            "b227cf1add6caca415b88f927fb10982b0cd846f71548f95071b65330e4024e1": {
                "Name": "cloudassembly-sddc-agent",
                "EndpointID": "405e7e8e1a4ad09b4cc99b0661454a4b0f32687152ca2346daf72f5a424dcd4d",
                "MacAddress": "02:42:c0:a8:01:03",
                "IPv4Address": "192.168.1.3/24",
                "IPv6Address": ""
            }
        },
        "Options": {},
        "Labels": {}
    }
]

Reboot and do the happy dance.

Happy not-coding.